
A Detailed Technical and Conceptual Article
Abstract
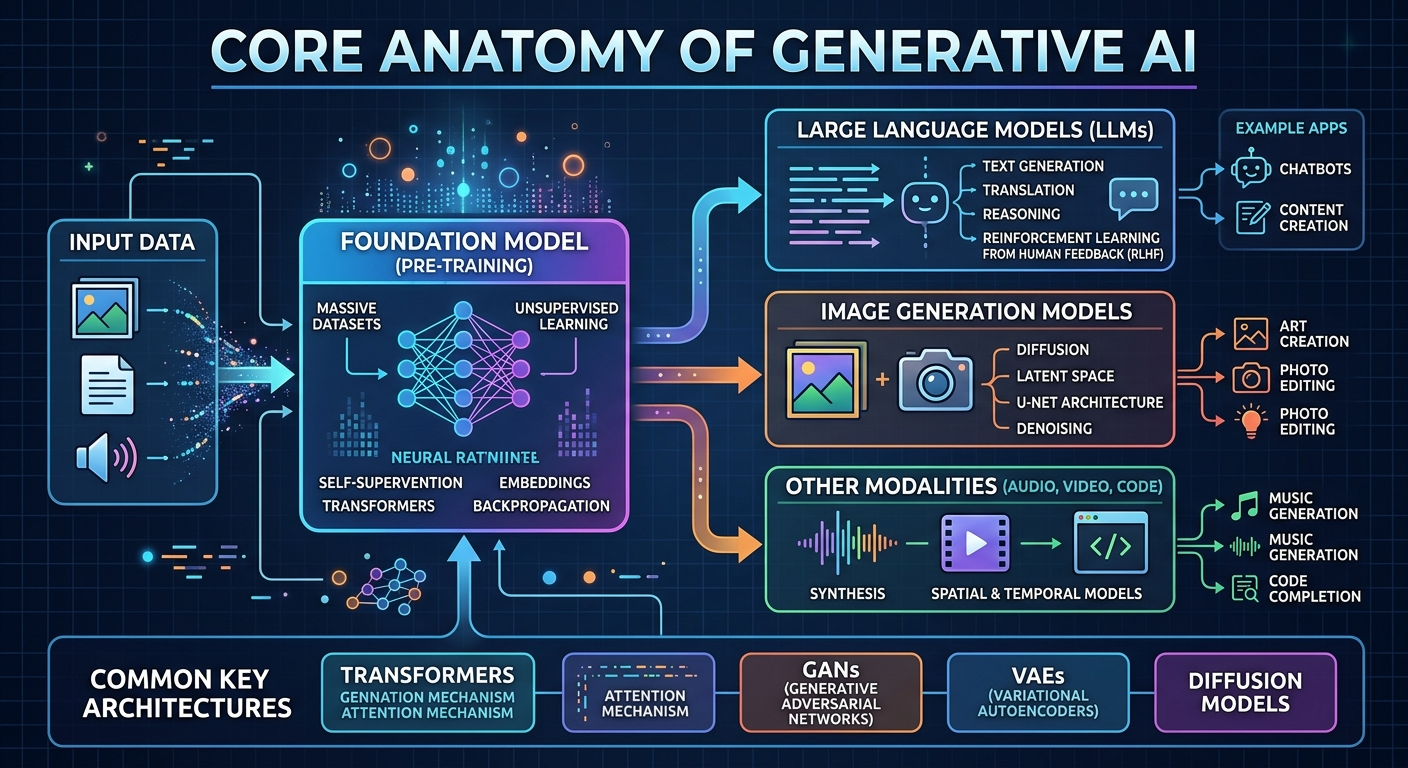
Generative Artificial Intelligence (Generative AI or GenAI) is a branch of artificial intelligence designed to create new content from learned patterns. It can generate text, computer code, images, audio, video, structured information and, increasingly, combinations of several modalities. Modern generative AI systems are not simply a single neural network. They are complex technological ecosystems containing data pipelines, tokenization systems, neural-network architectures, training infrastructure, model weights, inference engines, retrieval systems, safety mechanisms, application software and user interfaces.
The most important architectural development behind contemporary generative AI is the Transformer, introduced in 2017. Transformer-based systems use attention mechanisms to model relationships among elements of a sequence and can be trained efficiently at very large scale.
Understanding the “core anatomy” of generative AI therefore requires looking at the technology as a layered system—from raw data and computational hardware at the bottom, through mathematical representations and neural networks, to inference, applications and human interaction at the top.
1. Introduction: What Is Generative AI?
Traditional software generally follows explicit instructions:
Input → Rules/Algorithms → Output
Generative AI works differently:
Input → Learned Model → Probabilistic Generation → Output
Instead of programmers specifying every possible response, a generative model learns statistical and structural relationships from large collections of training data.
For example, a language model does not normally store a complete answer for every question. During training, it learns relationships among tokens, concepts, syntax, patterns and contexts. During generation, it uses those learned parameters to estimate what should come next.
A simplified representation is:
Prompt → Tokenization → Embeddings → Transformer → Probability Distribution → Token Selection → Generated Output
Modern systems add many more layers around this core.
Google describes foundation models as the central models upon which many generative-AI applications are built. These models can be trained on text, images, code or other forms of multimedia and subsequently adapted to particular tasks.
2. The Anatomical Layers of Generative AI
A useful way to understand generative AI is as a stack.
Layer 1 — Physical Infrastructure
- Data centers
- GPUs, TPUs and other accelerators
- CPUs
- Memory
- Storage
- Networking
- Electrical power
- Cooling
Layer 2 — Data
- Text
- Books
- Websites
- Code
- Images
- Audio
- Video
- Scientific information
- Structured databases
Layer 3 — Data Processing
- Cleaning
- Filtering
- Deduplication
- Classification
- Tokenization
- Transformation
- Annotation
Layer 4 — Representation
- Tokens
- Embeddings
- Vectors
- Positional information
- Latent representations
Layer 5 — Neural Architecture
- Transformer layers
- Attention
- Feed-forward networks
- Normalization
- Activation functions
- Output layers
Layer 6 — Model Parameters
- Weights
- Biases
- Learned representations
Layer 7 — Training
- Forward propagation
- Loss calculation
- Backpropagation
- Optimization
- Distributed training
Layer 8 — Model Adaptation
- Fine-tuning
- Instruction tuning
- Preference optimization
- Domain adaptation
Layer 9 — Inference
- Prompt processing
- Prefill
- Decoding
- Sampling
- KV caching
- Output generation
Layer 10 — External Knowledge and Tools
- Retrieval-augmented generation
- Search
- Databases
- APIs
- Calculators
- Software tools
Layer 11 — Safety and Evaluation
- Filtering
- Testing
- Monitoring
- Red-teaming
- Output evaluation
- Policy enforcement
Layer 12 — Application
- Chatbots
- Coding assistants
- Search systems
- Education
- Business applications
- Scientific systems
- Creative tools
Together these layers form the modern generative-AI ecosystem.
3. The Foundation: Computing Hardware
At the physical foundation of generative AI is computing infrastructure.
Large models require enormous amounts of numerical computation. Training and inference therefore depend heavily on specialized processors.
3.1 CPUs
Central Processing Units handle general-purpose computing.
They are important for:
- Operating systems
- Data preprocessing
- Application logic
- Networking
- Scheduling
- Database operations
- Supporting AI accelerators
However, large neural-network calculations are generally better suited to massively parallel accelerators.
3.2 GPUs
Graphics Processing Units are particularly effective for matrix and tensor calculations.
Neural networks perform enormous numbers of operations involving:
- Matrix multiplication
- Vector operations
- Tensor transformations
GPUs can execute many such operations simultaneously.
3.3 TPUs and Other AI Accelerators
Specialized AI accelerators are designed around the computational requirements of machine learning.
Google’s documentation notes that scaling modern Transformer models requires attention to computation, memory and communication between accelerators.
This illustrates an important principle:
Generative AI is simultaneously a software problem, a mathematical problem and a hardware problem.
4. Data: The Raw Material of Generative AI
Data is one of the most important components of the entire system.
A foundation model may be trained using enormous collections of:
- Text
- Books
- Web documents
- Code
- Images
- Audio
- Video
- Scientific material
- Mathematical content
- Other digital information
Google describes foundation models as being trained on very large datasets spanning text, images, code and multimedia.
But raw data cannot simply be dumped directly into a training system.
It must first be processed.
5. Data Preparation
A typical data pipeline can include:
Collection → Cleaning → Filtering → Deduplication → Transformation → Tokenization → Training Dataset
5.1 Cleaning
Data may contain:
- Duplicate material
- Corrupted files
- Irrelevant information
- Formatting problems
- Spam
- Machine-generated content
- Low-quality material
Cleaning attempts to improve the quality of the training corpus.
5.2 Deduplication
Repeated material can distort the training distribution and increase unnecessary computational expense.
Deduplication attempts to identify repeated or highly similar content.
5.3 Filtering
Data may be filtered according to quality, relevance, licensing requirements, safety requirements and other criteria.
The quality of the training data has a major influence on the resulting model.
6. Tokens: The Basic Units of Language Models
A language model does not directly process human sentences in the same form that people see them.
Text is converted into tokens.
A token may correspond to:
- A whole word
- Part of a word
- A character
- Punctuation
- A special symbol
Google’s current generative-AI glossary describes tokens as atomic units used by language models during training and inference.
For example, a sentence such as:
“Artificial intelligence learns patterns.”
may be divided into several tokens.
The exact division depends on the tokenizer and vocabulary.
The important point is:
Human language → Tokens → Numerical representations
7. Embeddings: Converting Symbols Into Mathematics
Neural networks operate on numerical values.
Therefore, tokens must be represented mathematically.
An embedding converts a token into a vector.
Conceptually:
Token → Vector
For example:
“computer” → [0.21, -0.44, 0.73, …]
The actual vectors used by large models contain many dimensions.
Embeddings allow the neural network to work with mathematical representations of linguistic and conceptual relationships.
Similar concepts can develop related representations, although embeddings should not be interpreted as simple dictionaries of meaning.
8. Positional Information
Language is not simply a bag of words.
Consider:
“The dog chased the cat.”
and
“The cat chased the dog.”
The same words occur, but their relationships differ.
Transformers therefore need information about the position or ordering of tokens.
Different Transformer systems use different positional-encoding strategies.
This allows the model to distinguish relationships such as:
Token A → Token B → Token C
rather than treating all tokens as unordered objects.
9. The Transformer: The Central Engine
The Transformer is arguably the most important architectural development underlying contemporary generative AI.
It was introduced in the landmark 2017 research paper Attention Is All You Need.
Transformer architectures use attention mechanisms to establish relationships between elements of a sequence. Google describes self-attention as allowing the architecture to determine which parts of a sequence are important in relation to others.
A simplified Transformer block can be represented as:
Input Embeddings
↓
Attention
↓
Normalization
↓
Feed-Forward Network
↓
Normalization
↓
Next Transformer Layer
This structure is repeated many times.
10. Attention
Attention is one of the fundamental mechanisms of modern generative AI.
The basic question is:
Which pieces of the input should influence the representation being calculated?
Suppose a sentence contains a pronoun referring to something mentioned earlier.
Attention allows the model to calculate relationships between different tokens.
Mathematically, attention is commonly represented using:
Q = Query
K = Key
V = Value
The classic attention formulation is:
Attention(Q,K,V) = softmax(QKᵀ / √dₖ)V
The equation describes how the model calculates relationships between queries and keys and uses those relationships to combine values.
11. Multi-Head Attention
Modern Transformer architectures generally use multiple attention heads.
Instead of calculating one type of relationship, different heads can learn different patterns.
One head might become useful for one type of syntactic relationship while another may capture a different contextual relationship.
The outputs are then combined.
Conceptually:
Input
↓
Head 1
Head 2
Head 3
…
Head N
↓
Concatenate
↓
Linear Transformation
↓
Output
This gives the architecture a richer mechanism for processing relationships.
12. Feed-Forward Networks
Attention is only one major component of a Transformer.
Transformer layers also contain feed-forward neural networks.
These networks apply learned transformations to the representations produced by attention.
A simplified structure is:
Input → Linear Transformation → Activation → Linear Transformation → Output
The feed-forward component provides additional computational capacity for transforming learned representations.
13. Parameters: The Learned Memory of the Model
A model’s parameters are numerical values adjusted during training.
They include enormous collections of learned weights.
A simplified neural network might contain:
Input → Weight → Neuron → Weight → Output
A modern large model contains vastly more parameters.
Parameters are not equivalent to a database containing one complete answer for every question.
Instead, they encode learned statistical relationships and transformations.
This distinction is essential for understanding why a generative model can produce novel combinations of information.
14. Training: How the Model Learns
Training is the process through which model parameters are adjusted.
For an autoregressive language model, a simplified training objective is:
Predict the next token from the preceding context.
For example:
The Earth revolves around the ___
The model may assign probabilities to possible next tokens.
The training system compares the prediction against the expected training token and calculates a loss.
15. Loss Function
The loss function measures how far the model’s prediction is from the desired training target.
For language modeling, cross-entropy loss is commonly used.
Conceptually:
Prediction → Compare With Target → Calculate Error
The objective is to minimize this error across the training data.
16. Backpropagation
Once the system calculates the error, backpropagation determines how the model’s parameters contributed to that error.
The process is approximately:
Input
↓
Forward Pass
↓
Prediction
↓
Loss
↓
Backpropagation
↓
Gradient Calculation
↓
Parameter Update
This process is repeated enormous numbers of times.
Google’s explanation of GPT similarly describes training through repeated exposure to data and adjustment based on prediction errors using backpropagation.
17. Optimization
The calculated gradients are used by an optimization algorithm to update model parameters.
A simplified equation is:
New Weight = Old Weight − Learning Rate × Gradient
The learning rate controls how aggressively parameters are changed.
Training therefore becomes a continuous mathematical process of improving the model’s predictions.
18. Pretraining
The first major stage is generally called pretraining.
The model processes enormous quantities of data and learns general patterns.
For language models, this can include learning:
- Grammar
- Syntax
- Vocabulary
- Associations
- Code structures
- General knowledge patterns
- Reasoning-like patterns
- Relationships between concepts
The resulting foundation model can then be adapted to specific applications.
IBM describes generative AI development as involving training, tuning, and subsequent generation/evaluation/retuning stages.
19. Fine-Tuning and Instruction Tuning
A pretrained model may not automatically behave like a useful assistant.
Additional training can make it better at following instructions or performing specialized tasks.
This can include:
- Supervised fine-tuning
- Instruction tuning
- Domain adaptation
- Preference optimization
For example, a general model could be adapted to work more effectively with:
- Programming
- Scientific literature
- Legal documents
- Customer service
- Education
- Enterprise information
20. Alignment and Human Preferences
A generative model can produce many possible outputs.
The system therefore needs mechanisms to encourage desirable behavior.
Training and evaluation may consider:
- Helpfulness
- Accuracy
- Safety
- Relevance
- Instruction following
- Consistency
Preference-based methods can help optimize models toward preferred outputs.
Google’s documentation notes that reinforcement-learning approaches can be used to optimize generative systems for qualities such as coherence, safety and usefulness.
21. Inference: When the Model Actually Generates
Training creates the model.
Inference uses the model.
When a person enters a prompt, the system executes the trained neural network to generate an answer.
A simplified process is:
User Prompt
↓
Tokenization
↓
Transformer Processing
↓
Probability Distribution
↓
Token Selection
↓
Next Token
↓
Repeat
↓
Final Response
Modern inference commonly involves a prefill stage, where the prompt is processed, followed by decoding, where output tokens are generated sequentially. KV caching can reduce repeated computation during generation.
22. Probability and Token Generation
At each generation step, the model produces probabilities for possible next tokens.
Conceptually:
| Candidate | Probability |
|---|---|
| technology | 0.42 |
| science | 0.25 |
| system | 0.17 |
| computer | 0.09 |
| other | 0.07 |
The system then selects a token according to its generation strategy.
This process repeats.
Therefore:
One token → next token → next token → next token
can eventually become a paragraph, article, program or conversation.
23. Temperature and Sampling
Generative systems may use sampling parameters to influence output behavior.
A lower-temperature configuration generally makes the probability distribution more concentrated, while a higher temperature can produce more variation.
Other techniques include:
- Top-k sampling
- Top-p sampling
- Greedy decoding
- Beam-related methods in some architectures
These mechanisms influence how the model moves from probabilities to actual output.
24. Context Window
The model does not necessarily have unlimited access to every piece of information ever encountered.
During an interaction, it receives a context consisting of tokens.
The context may include:
- System instructions
- User messages
- Previous conversation
- Retrieved documents
- Tool results
- Other relevant information
The maximum amount that can be processed is determined by the model and serving system.
The context window is therefore a critical component of modern generative AI.
25. KV Cache
During autoregressive generation, the model repeatedly processes previous context.
A key-value cache, commonly called KV cache, stores intermediate attention information so that the system does not have to recompute everything from scratch for every generated token.
This is especially important for long conversations and high-throughput AI services.
Inference efficiency therefore depends heavily on:
- Memory bandwidth
- Accelerator memory
- KV-cache management
- Parallelism
- Batch size
- Model architecture
- Quantization
26. Retrieval-Augmented Generation
A foundation model’s learned parameters are not the same thing as a continuously updated database.
Retrieval-Augmented Generation, or RAG, connects a generative model with external information.
A simplified architecture is:
User Question
↓
Retriever
↓
Search External Knowledge
↓
Relevant Documents
↓
Prompt Augmentation
↓
Generative Model
↓
Answer
IBM identifies four major RAG components: a knowledge base, retriever, integration layer and generator.
27. Embeddings in RAG
RAG commonly uses embedding models to convert documents into vectors.
A document can be divided into smaller chunks.
Each chunk is represented as a vector.
When the user asks a question, the question is also converted into a vector.
The system then searches for vectors that are semantically relevant.
Conceptually:
Document → Chunk → Embedding → Vector Database
and:
Question → Embedding → Similarity Search → Relevant Chunks
Those chunks can then be supplied to the generative model.
28. Multimodal Generative AI
Generative AI is no longer restricted to text.
Modern multimodal systems can work across combinations of:
- Text
- Images
- Audio
- Video
- Code
Google describes multimodal models as systems capable of processing multiple forms of input and generating or reasoning across multiple modalities.
A multimodal architecture can therefore be represented as:
Text Encoder
Image Encoder
Audio Encoder
Video Representation
↓
Shared/Integrated Representation
↓
Generative Model
↓
Text / Image / Audio / Other Output
The exact architecture varies considerably between models.
29. Image Generation
Generative image systems use architectures that differ from ordinary language models.
One important family is the diffusion model.
A simplified diffusion process is:
Real Image → Add Noise → Noisy Representation
During generation:
Noise → Iterative Denoising → Generated Image
IBM describes diffusion models as systems trained around the process of adding noise and learning to reverse that process to produce desired outputs.
Some modern systems combine diffusion-like mechanisms with Transformer-based components.
30. Audio and Speech Generation
Generative AI can also operate on sound.
Systems may process representations of:
- Speech
- Music
- Environmental sounds
- Acoustic signals
They can generate:
- Speech
- Music
- Sound effects
- Transcriptions
- Voice-like outputs
The underlying architecture can involve Transformers, diffusion methods, neural codecs and other specialized models.
31. Video Generation
Video generation is substantially more complex because video contains both:
Spatial information
and
Temporal information
The system must model relationships across frames.
A conceptual representation is:
Frame 1 → Frame 2 → Frame 3 → … → Frame N
while maintaining:
- Objects
- Motion
- Scene consistency
- Temporal relationships
- Visual structure
Video-generation systems therefore require substantial computational resources.
32. Generative AI Agents
A modern AI application may extend beyond simply generating text.
An agentic system can combine:
Model + Memory + Tools + Planning + External Data + Actions
For example:
User Request
↓
AI Model
↓
Reasoning/Planning
↓
Tool Selection
↓
External Tool
↓
Result
↓
Model
↓
Final Response
This turns a generative model into a component of a larger computational system.
33. Tools and Function Calling
A model can be connected to external software tools.
Examples include:
- Databases
- Search systems
- Calculators
- Code execution environments
- Enterprise applications
- Scheduling systems
- APIs
The model determines what information or operation is required, while the external tool performs the actual operation.
This distinction is important:
The model does not necessarily perform every action itself; it can orchestrate external software.
34. Safety Architecture
Generative AI systems require safety mechanisms around the model.
These can operate before, during and after generation.
Input controls
Check potentially problematic prompts.
Model controls
Train or configure the system to respond appropriately.
Output controls
Evaluate generated content before presenting it.
Monitoring
Track system performance and unusual behavior.
Human oversight
Some applications require human review.
Safety therefore should not be viewed as one filter placed at the end.
It is better understood as a layered architecture.
35. Evaluation
A model must be tested before and after deployment.
Evaluation can examine:
- Accuracy
- Reasoning
- Coding
- Mathematical performance
- Knowledge
- Robustness
- Bias
- Safety
- Instruction following
- Latency
- Cost
- Reliability
Benchmark scores are useful, but they do not fully describe real-world performance.
A production system must also be evaluated against actual user requirements.
36. Hallucination
One of the important limitations of generative AI is hallucination.
A model can generate information that sounds convincing but is incorrect.
This occurs partly because generation is based on learned statistical patterns rather than a guaranteed truth-verification mechanism.
Possible mitigation approaches include:
- Retrieval
- Tool use
- Verification
- Structured generation
- Human review
- Better training
- Specialized evaluation
RAG can provide external information to a model, but it does not automatically guarantee correctness.
37. The Application Layer
The end user normally interacts with an application rather than directly with the neural network.
The application may contain:
User Interface
↓
Application Server
↓
Prompt Management
↓
Model/API
↓
Tools or Retrieval
↓
Model
↓
Response Processing
↓
User Interface
This is why a chatbot is more than just an LLM.
The visible application is the uppermost layer of a much larger technical stack.
38. The Complete Anatomy
A useful overall architecture is:
                     HUMAN USER
                         │
                         ▼
                 APPLICATION / UI
                         │
                         ▼
                PROMPT / CONTEXT
                         │
                         ▼
              ┌──────────────────┐
              │ AI ORCHESTRATION │
              └──────────────────┘
                  │          │
             ┌────┘          └─────┐
             ▼                      ▼
        RETRIEVAL                TOOLS
             │                      │
             └──────────┬───────────┘
                        ▼
                FOUNDATION MODEL
                        │
              ┌─────────┴─────────┐
              ▼                   ▼
          TRANSFORMER          OTHER MODEL
              │              ARCHITECTURES
              ▼
          ATTENTION
              │
              ▼
       NEURAL NETWORK LAYERS
              │
              ▼
       LEARNED PARAMETERS
              │
              ▼
        TRAINING PROCESS
              │
              ▼
          TRAINING DATA
              │
              ▼
       COMPUTING HARDWARE
              │
              ▼
       DATA CENTER / CLOUD
This illustrates the central idea:
Generative AI is an ecosystem, not merely a model.
39. Training Infrastructure
Large-scale training requires distributed computing.
A model may be divided across many accelerators.
Training can involve:
- Data parallelism
- Tensor/model parallelism
- Pipeline parallelism
- Sharding
- Distributed optimization
As model size increases, communication between accelerators becomes increasingly important.
Google’s TPU documentation emphasizes the interaction between computation, memory and inter-chip communication when scaling Transformer systems.
40. Memory Hierarchy
Generative AI depends heavily on memory.
Important levels include:
- Processor registers
- Cache
- Accelerator memory
- System RAM
- High-speed storage
- Distributed storage
The model’s weights, activations and KV cache must be moved through this hierarchy efficiently.
Therefore:
AI performance ≠ processor speed alone.
It also depends on:
Compute + Memory + Bandwidth + Communication + Software
41. Quantization
Large models can require substantial memory.
Quantization reduces numerical precision.
For example, model parameters may be represented using lower-precision numerical formats.
Potential benefits include:
- Lower memory requirements
- Faster inference
- Lower hardware cost
- Greater deployment flexibility
The trade-off is that excessive compression can affect model quality.
42. Model Compression
Other optimization techniques include:
- Pruning
- Distillation
- Quantization
- Weight sharing
- Efficient architectures
The goal is often to preserve as much useful capability as possible while reducing computational requirements.
43. Open and Closed Models
Generative AI models can broadly be delivered through different access models.
Closed or proprietary models
The provider controls the underlying model and infrastructure.
Users commonly access the model through:
- Web applications
- APIs
- Enterprise services
Open-weight models
Model weights may be made available under particular licenses.
Organizations can potentially deploy or customize them depending on the license and technical requirements.
The distinction between “open source” and “open weights” is important because availability of model weights does not necessarily mean every component of the training system is openly available.
44. Generative AI as a Mathematical Machine
At its deepest level, generative AI can be understood as a very large mathematical transformation system.
The simplified abstraction is:
Input X
↓
Neural Network f(X; θ)
↓
Probability Distribution P(Y|X)
↓
Output Y
where:
- X = input
- θ = learned parameters
- Y = generated output
Training attempts to find parameters θ that produce useful predictions.
Inference applies those learned parameters to new inputs.
45. Generative AI Is Not a Human Brain
It is tempting to describe AI models as artificial brains.
The analogy can be useful at a very broad level, but it has limitations.
A Transformer is not a biological brain.
Its fundamental operations are numerical:
- Matrix multiplication
- Vector operations
- Attention
- Nonlinear transformations
- Probability calculations
- Optimization
The model’s apparent intelligence emerges from the interaction of enormous numbers of learned parameters and computational operations.
46. Why Scale Matters
Modern generative AI has been strongly influenced by scaling.
Increasing:
- Training data
- Model parameters
- Computational resources
- Context length
- Training quality
- Architecture quality
can produce significant changes in capability.
However, bigger does not automatically mean better.
A useful system must balance:
Capability + Accuracy + Cost + Speed + Reliability + Safety
47. The Difference Between Training and Inference
This distinction is fundamental.
| Training | Inference |
|---|---|
| Creates/updates model | Uses trained model |
| Extremely computationally intensive | Usually less expensive per request |
| Updates parameters | Parameters generally remain fixed |
| Processes training data | Processes user/application input |
| Uses backpropagation | Primarily forward computation |
| Happens during model development | Happens whenever users query the model |
IBM similarly distinguishes inference from training as a forward-generation process in which learned parameters are not updated.
48. The Difference Between an AI Model and an AI Application
An AI model is the learned computational system.
An AI application is the larger software product that uses one or more models.
For example:
Model
→ Transformer
Application
→ User interface + authentication + model + retrieval + tools + databases + monitoring + safety + billing + analytics
This distinction is critical when designing commercial AI products.
49. The Generative AI Technology Stack
The entire ecosystem can therefore be represented as:
Level 1 — Energy
Electricity and power infrastructure
Level 2 — Physical Infrastructure
Data centers, cooling and networking
Level 3 — Compute
GPUs, TPUs and AI accelerators
Level 4 — Storage and Memory
HBM, RAM, SSDs and distributed storage
Level 5 — Systems Software
Operating systems, drivers, compilers and runtimes
Level 6 — AI Frameworks
Libraries for tensor computation, training and inference
Level 7 — Data
Training and knowledge datasets
Level 8 — Models
Transformers, diffusion models and multimodal architectures
Level 9 — Model Adaptation
Fine-tuning, instruction tuning and preference optimization
Level 10 — Inference
Serving, decoding, caching and optimization
Level 11 — Knowledge
RAG, vector databases and enterprise data
Level 12 — Tools
APIs, databases and external applications
Level 13 — Applications
Chatbots, assistants, search, coding and creative applications
Level 14 — Human Interaction
The final interface between AI and society
50. The Future Anatomy of Generative AI
The architecture is continuing to evolve.
Future systems are likely to emphasize combinations of:
- Larger and more efficient models
- Smaller specialized models
- Multimodal reasoning
- Longer context
- Retrieval
- Tool use
- Agentic systems
- On-device AI
- Specialized accelerators
- Efficient inference
- Better evaluation
- Stronger safety systems
The most important development may therefore not be simply creating a larger model.
It may be creating better integrated AI systems.
51. A Simple Mental Model
For someone learning generative AI, the entire field can be reduced to ten questions:
1. What data does the system learn from?
Data
2. How is the data represented?
Tokens and embeddings
3. What mathematical structure processes it?
Neural network
4. What architecture dominates modern language generation?
Transformer
5. How does it understand relationships?
Attention
6. How does it learn?
Optimization and backpropagation
7. What does it learn?
Parameters
8. How does it produce new content?
Inference and token generation
9. How does it obtain information outside its learned parameters?
Retrieval and tools
10. How does it become a usable product?
Application software, infrastructure, evaluation and safety
52. Conclusion
The core anatomy of generative AI is best understood as a layered technological organism.
At the bottom are:
Electricity → Data Centers → Accelerators → Memory → Networking
Above them are:
Data → Processing → Tokens → Embeddings → Neural Networks → Parameters
At the center is:
Transformer → Attention → Learned Representations → Generation
Around the model are:
Retrieval → Tools → Databases → APIs → Safety → Evaluation
At the top is:
Application → User → Human-AI Interaction
The extraordinary capabilities of modern generative AI emerge from the interaction of all these components rather than from any single algorithm.
The Transformer provides a powerful computational architecture; training converts data into learned parameters; inference turns those parameters into generated outputs; retrieval and tools extend the system beyond the model itself; and application infrastructure transforms the underlying technology into something people can actually use.
Consequently, the most accurate definition of modern generative AI is not simply “a model that generates content.”
It is a complete computational ecosystem that combines data, mathematics, neural networks, specialized hardware, software infrastructure, knowledge retrieval, generation, evaluation and human interaction to produce new information and actions.
That is the true core anatomy of Generative AI.
Key Reference Points
- Google Cloud explains that modern foundation models form the core of many generative-AI applications and can support text, image, audio, video and other modalities.
- Google Cloud’s explanation of GPT highlights the Transformer and self-attention as central mechanisms for modern language generation.
- IBM describes generative-AI development through training, tuning, generation and evaluation, while identifying Transformers and diffusion models as major generative architectures.
- IBM’s RAG architecture explains how external knowledge can be retrieved and supplied to a foundation model at runtime.
- Modern inference involves prompt processing, sequential decoding and techniques such as KV caching to improve performance.

Be First to Comment